
MAA
-
Posts
130 -
Joined
-
Last visited
-
Days Won
1
Content Type
Profiles
Forums
Events
Everything posted by MAA
-
If SHA3 can't be optimized, I suggest adding BLAKE3, which supports practically unlimited degree of parallelism (both SIMD and multithreading) https://shattered.io/blake3-vs-sha-512-2026/
-
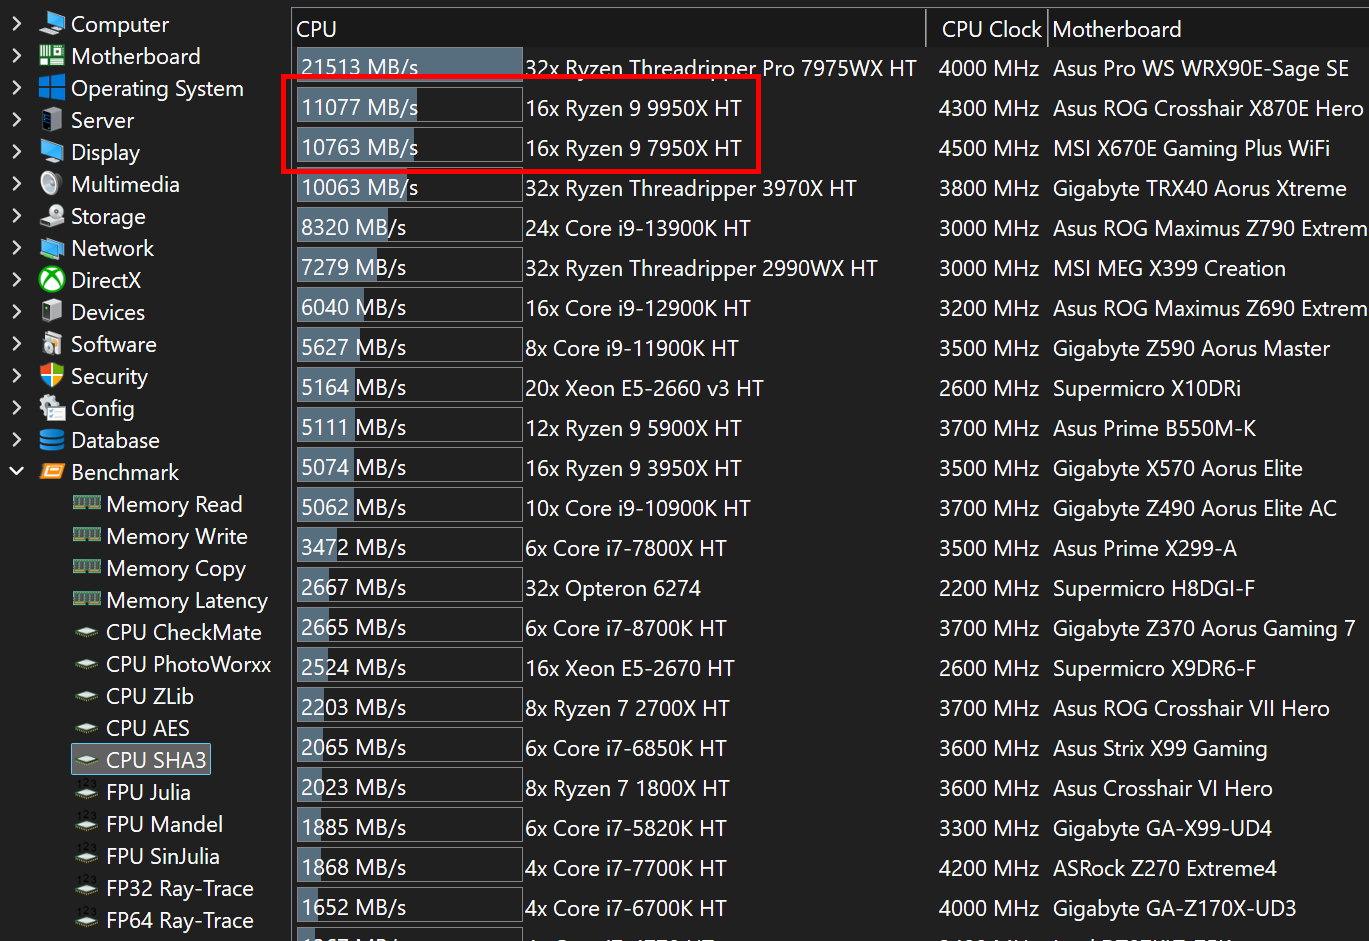
I also discovered some strange SHA3 results. Why doesn't the Zen 5 architecture gain an advantage over Zen 4? Why doesn't the 512-bit datapath gain an advantage over the 256-bit datapath? Perhaps additional AVX-512 optimizations are required?
-
Hello, When the switch to version 8 was made, I expected updated benchmarks; however, that didn't happen, and CheckMate remains the only new benchmark to date. I had already suggested updating certain benchmarks, but I’ve now consolidated those ideas into a single post. CPU: CheckMate - OK PhotoWorxx - should be replaced, for example, with the VVC/EVC/AV2 encoding benchmark Zlib - must be replaced with a faster implementation, for example Zlib-ng https://github.com/zlib-ng/zlib-ng AES - OK +However, it is also necessary to add the ChaCha20 (used in TLS 1.3) benchmark, which is relevant for processors without AESNI https://en.wikipedia.org/wiki/ChaCha20-Poly1305 +In addition, it is desirable to add the new AEGIS benchmark (proposed for future use with TLS) https://cfrg.github.io/draft-irtf-cfrg-aegis-aead/draft-irtf-cfrg-aegis-aead.html SHA3 - OK +However, it is also necessary to add a SHA-2 benchmark capable of utilizing SHA instructions https://en.wikipedia.org/wiki/SHA_instruction_set FPU: Julia - OK Mandel - must be refined for better multithreading support https://forums.aida64.com/topic/13433-threadripper-7975wx-bench-results/#comment-63473 SinJulia - OK FP32 RayTrace - OK FP64 RayTrace - OK +It would also be interesting to see the LINPACK benchmark (or at least DGEMM/SGEMM) NPU: some benchmark needs to be added
-
The funniest thing is that Ryzen systems don't have a North Bridge. Why are you still using the outdated name instead of MCLK/UCLK/FCLK?
-
Hello, Please add wide gamut test to Monitor Diagnostics Tests (nowadays, many displays have almost 100% DCI-P3 coverage)
-
Hello, How do you get the L2 BPC value? as far as I know, the CPU core can only 64 B/cycle to L2 64*16=1024

-
Could you please explain why you haven't added this support yet? Most monitors and videocards support 10-bit color these days.
-
Hello, Does AIDA support 10-bit color? (For example, for Monitor Diagnostics tool) cannot find this info in manual...
-
Hello, Under CPU stress test "GPU2:GPU" show same value as 'CPU package'

-
Hello, Can you add FAN sensors for Asus ROG laptops?
-
Hello, Where can I see information about the CPU performance levels? (Intel PL1/PL2, AMD SPL/sPPT/fPPT)
-
and another question - is the random read benchmark really random? I tested the HDD with the linear read and random read benchmarks (4 KB block), and in both cases I got 20 MB/s, which cannot be.
-
Please add the display of the results not only in MB/s, but also in IOPs
-
Question about frenquencies displayed in benchmarks
MAA replied to frwho's topic in Benchmarking, system performance
In this case, you should be consistent and specify the base frequency for the processor under test. (you are currently displaying the turbo frequency) -
Incorrect memory freq/timings (Ryzen 9 9955HX)
MAA replied to MAA's topic in Benchmarking, system performance
It is unlikely that a single measurement of the memory frequency can significantly affect the benchmark result. In any case, you can increase the duration of the benchmark to reduce this impact. -
Hello, Memory benchmarks show incorrect frequency (ddr5-3197) and timings. In fact, ddr5-5600 memory modules are installed. I assume that Aida shows the frequencies and timings in idle time, instead of the values during the benchmark.

-
Can you add LINPACK benchmark to the GPGPU and CPU FPU benchmarks?
-
missing a lot of information, incorrect dram latency... is this "fine"?

-
New cache and memory benchmarks in AIDA64 v3.00
MAA replied to Fiery's topic in Benchmarking, system performance
Hello, Why is the Memory Write speed 79 percent faster than the Memory Read speed?
-
For now I suggest using uvg266 https://github.com/ultravideo/uvg266 unlike x265, uvg266 scales very well to the number of cores:

-
Hello, Why is the Memory Write speed 67 percent faster than the Memory Read speed?
-
Hello, Suggestion - release a standalone CPU/GPU benchmark based on your ray tracing engine (from FP32/FP64 Ray-Trace benchmark) with visualization (similar to Cinebench 2024) this will increase mentions and popularity of AIDA

-
what exact method do you use to measure flops/iops? matrix multiplication or something else?
-
We will add the Bytes per Clock (BPC) bandwidth option to the right-click context menu in the next AIDA64 beta update In this case, the "Latency" should also switch to "clocks"
-
As for the per core request, I'm afraid our multi-threaded bandwidth benchmarks do not expose the per-core performance results, so we cannot show them on the UI. But modern processors have different cores (Intel P/E, Zen 5/5c), and it would be interesting to be able to get results for different types of cores